Benchmark · June 12, 2026 · Updated October 18, 2026 · 6 min read
KodeGraph helps Kaptain find the right code with fewer tokens
Kaptain includes KodeGraph, a model-agnostic code index that helps agents reach the right working set with fewer wasted model tokens. In the clean June 25 comparison, on one exact-lookup task, Kaptain + KodeGraph used 78.1% fewer total Codex tokens than Direct Codex, with the same 1.000 gold-file recall.
Why this matters
When an AI assistant works on a real codebase, the expensive part is not one lookup. It is the loop: search, miss, ask again, open more files, then finally get enough context to act. Every extra loop spends tokens, time, and local compute.
Kaptain builds KodeGraph into its workflow so models spend fewer tokens finding code while you build real projects. KodeGraph indexes your project’s files, symbols and calls, and models query it with the kodegraph_* tools instead of reading whole files.
The primary benchmark shown here is the clean June 25 comparison: one exact lookup, the same 1.000 gold-file recall, and lower total Codex spend with Kaptain + KodeGraph. It ran on an earlier KodeGraph build. A July 5 run of the Go engine that Kaptain now ships is summarised under Token cost.
Additional KodeGraph runs are used as supporting evidence for retrieval quality and workflow behavior, but the cost claim is anchored to full-session Codex tokens rather than a single isolated payload.
The verdict at a glance
Fewer Codex tokens
June 25, one exact lookup: 11,438 total Codex tokens with Kaptain + KodeGraph versus 52,241 for Direct Codex.
Gold-file recall
Both runs reached the gold working set, keeping the comparison focused on cost, speed, and workflow efficiency.
Codex tool calls
In that run, Kaptain ran the KodeGraph lookup itself and handed Codex the result, versus 2 tool calls for Direct Codex.
Wall time
Kaptain + KodeGraph completed the exact lookup in 5.5 seconds versus 13.1 seconds for Direct Codex.
Retrieval quality
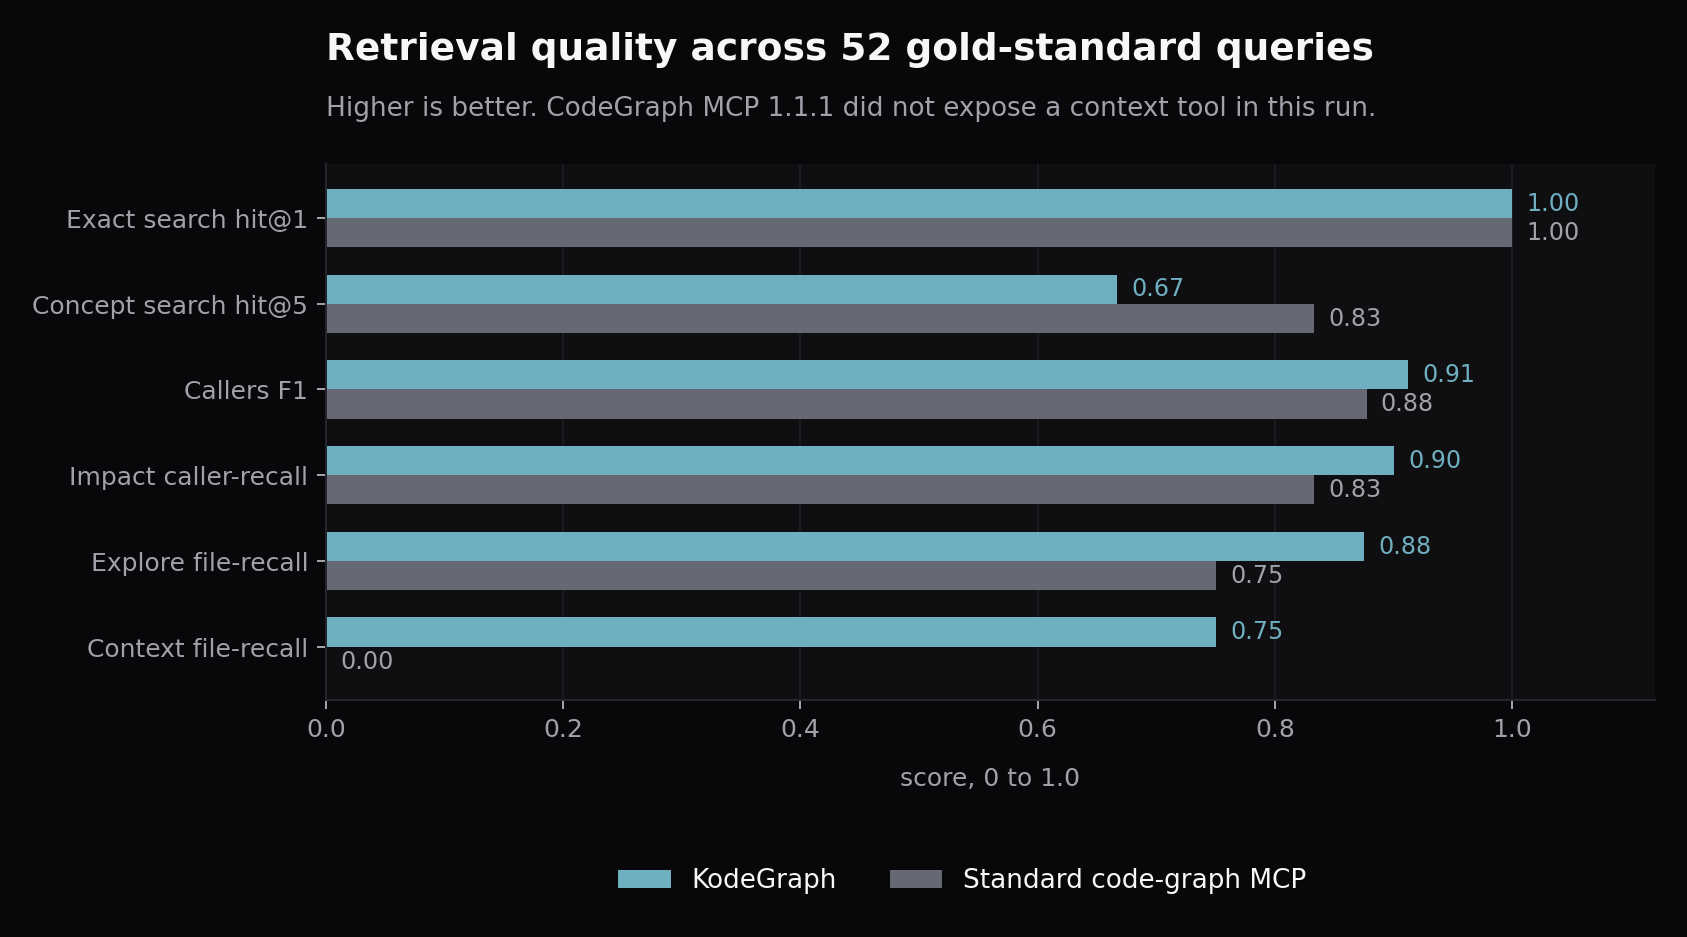
"Quality" here means: when you ask the engine something, does it return the right answer? A score of 1.0 is perfect, so higher is better. KodeGraph is teal; the standard code-graph MCP is slate. This June 25 run used 52 gold-standard queries per engine, with a neural embedding model for semantic search.
Finding the right code
This is the question that matters most: if Kaptain is going to help with a codebase, it has to retrieve the right evidence. These tests ask whether the engine can identify callers, estimate change impact, and gather the files needed for a task.
On "who calls this" and change-impact, KodeGraph is ahead in this run. On gathering code for a task, KodeGraph's context and explore paths give the agent a strong working set before the model spends more turns. That is what improves file work: fewer blind searches before the model can read, modify, and verify the relevant code. The standard tool led concept search, memory use and raw per-call speed in the same run.
Token cost: Kaptain reduces full Codex spend
Tokens are operating cost. They affect user spend, latency, and how far a workflow can scale before it becomes too expensive. The clean June 25 benchmark compares Direct Codex against Kaptain + KodeGraph on the same exact lookup with the same 1.000 gold-file recall. In that run, Kaptain ran the KodeGraph lookup first and handed Codex the result.
| Metric | Direct Codex | Kaptain + KodeGraph | Result |
|---|---|---|---|
| Gold-file recall | 1.000 | 1.000 | Same answer quality |
| Total Codex tokens | 52,241 | 11,438 | 78.1% lower |
| Uncached input tokens | 19,444 | 9,377 | 10,067 fewer |
| Output tokens | 413 | 141 | 272 fewer |
| Codex tool calls | 2 | 0 | Kaptain ran the lookup first |
| Wall time | 13.1s | 5.5s | Faster completion |
The Go engine, July 5. A later run measured Codex calling Kaptain’s KodeGraph tools itself, the way models use them in Kaptain now, on three Go-repository tasks. All three conditions reached 1.000 recall. With KodeGraph, Codex averaged 159,203 total tokens, against 176,861 on its own (10.0% fewer) and 322,911 with the standard code-graph MCP (50.7% fewer). It was not faster: 53.8 seconds on average, against 48.7 for Direct Codex.
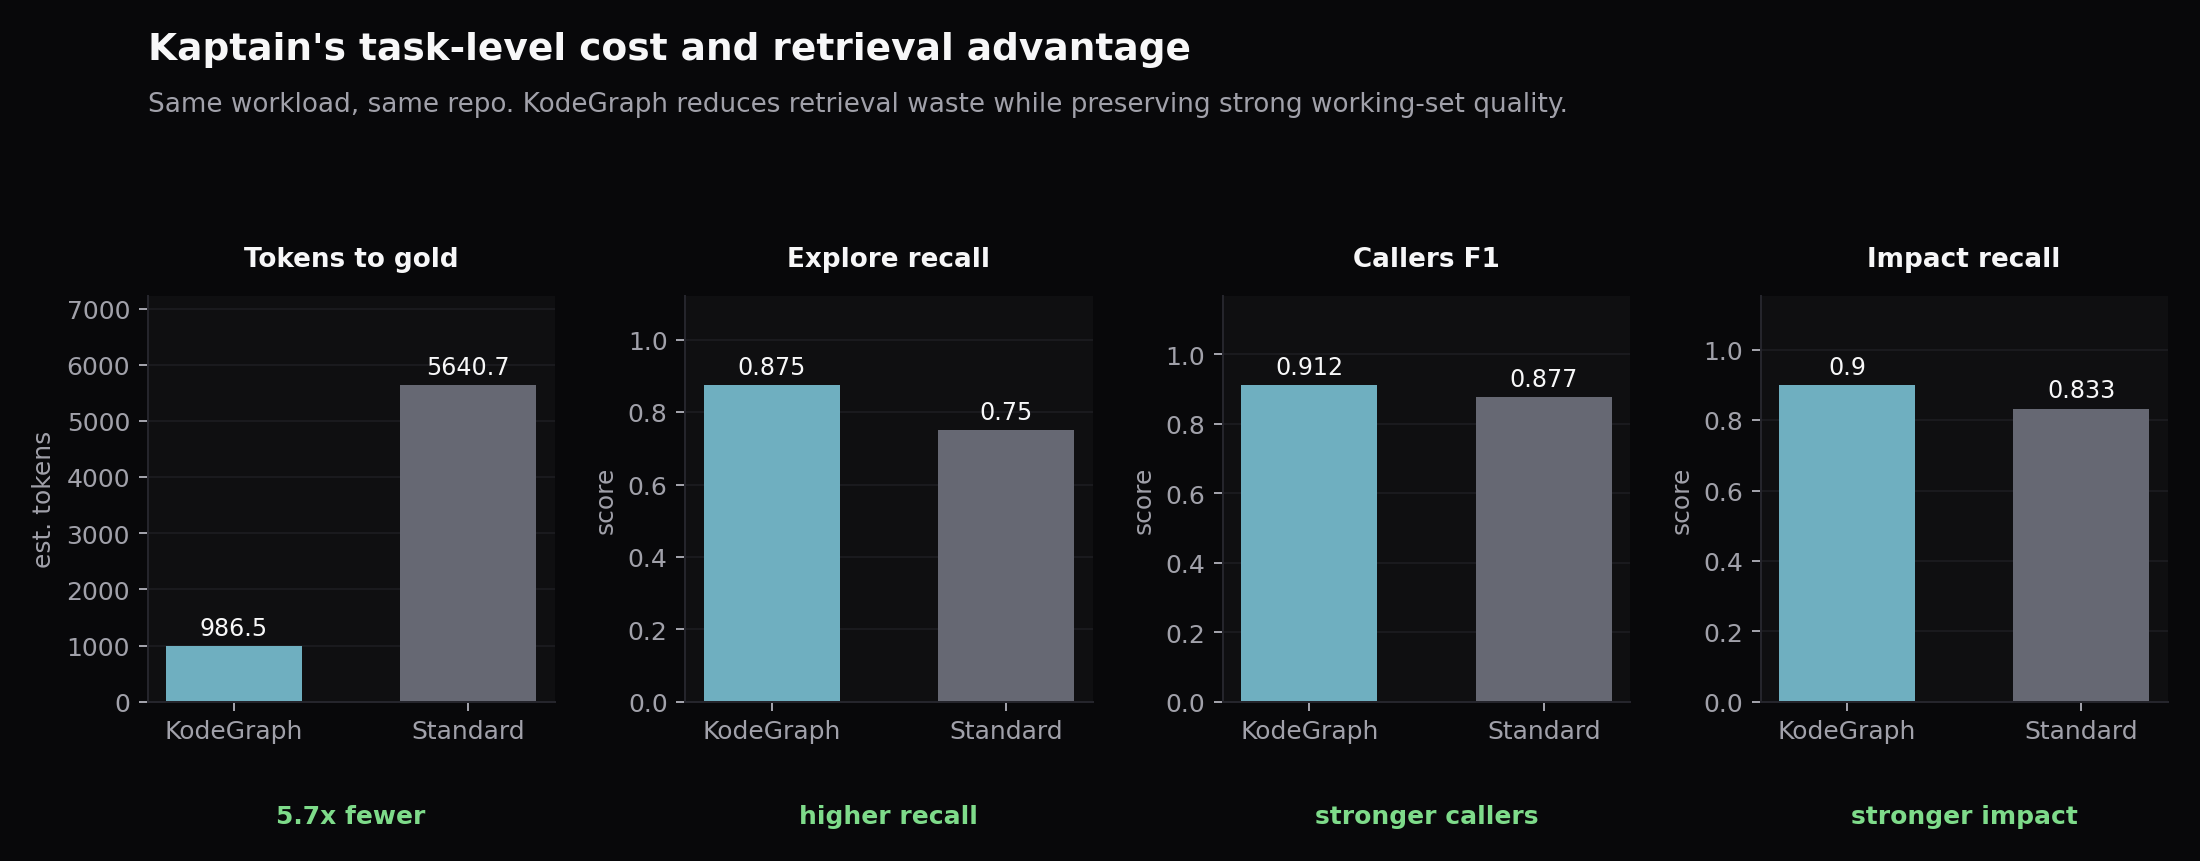
The token data separates payload size from payload value. Kaptain's advantage is workflow-level: fewer avoidable model tokens, fewer tool loops, and a cleaner route to the working set.
The cost advantage in the workflow
Kaptain is local-first, but the bigger user-facing cost is the repeated retrieval loop: every miss can trigger another model turn and another payload. KodeGraph reduces that waste by shaping context around the task before the model starts coding.
Why this makes Kaptain stronger
Beyond the head-to-head metrics, KodeGraph is designed as a model-agnostic context layer. It strengthens Kaptain's own agent workflows and can enrich other connected AI systems with better retrieval context. That gives Kaptain an advantage over generic code-graph tooling where code work actually starts: selecting the right project context before a model spends tokens reasoning over it.
| Capability | KodeGraph | Standard MCP |
|---|---|---|
| Symbol search, callers, callees, impact, explore | ✓ | ✓ |
| Dedicated context tool in MCP surface | ✓ | — |
| Task context within a token budget | ✓ | — |
| Will not index a home folder or a huge tree by accident | ✓ | — |
| Project graph view (God's Eye) + terminal commands | ✓ | CLI only |
| Index and keyword search need no external runtime | in-process | needs Node |
| Model-agnostic context layer | ✓ | — |
| Can enrich other connected AI workflows | ✓ | partial |
What Kaptain users get
KodeGraph matters because it is a native Kaptain capability. That changes the user experience in four practical ways:
- Codebase reading by query. Models find the relevant code with KodeGraph’s search, callers, callees and impact queries instead of opening whole files.
- Lower wasted token spend.
kodegraph_contextreturns only the code relevant to a task, within a token budget, so useful context does not turn into token bulk. - Model-agnostic leverage. Every model route in Kaptain uses the same KodeGraph tools, so the gain carries across model choices.
- Part of Kaptain. The index ships with Kaptain and re-indexes changed files in the background. Semantic search uses an embedding model chosen under Settings › Model Handling › KodeGraph Embedder: Kaptain’s built-in model, one you have installed, or an endpoint you set. With none, KodeGraph ranks by keywords.
Sources
- Token comparison, June 25, 2026: CHYNJ internal benchmark report. One exact-lookup task on the Kaptain codebase, with an earlier KodeGraph build. Direct Codex used 52,241 total tokens; Kaptain + KodeGraph used 11,438, with the same 1.000 gold-file recall.
- Retrieval quality and the charts, June 25, 2026: CHYNJ internal benchmark report. 52 queries per engine on the same repository.
- Go engine, July 5, 2026: CHYNJ internal benchmark report. Three Go-repository tasks, each in a fresh Codex session.